A Galactic Singularity
Abstract
Since the mathocalypse began on 2026-10-06, it has been a strange and unsettling time. Amongst other things, OpenAI announced , i.e., there exists an time algorithm for matrix multiplication. But hold on, doesn’t dramatically faster matrix multiplication mean dramatically faster training of LLMs .. don’t you realise !?! The singularity is here!!!
This at least, has given me some comic relief from deciding how much to increase my by.
1 The Hype
Like any sensible person, I was astounded by OpenAI’s mathdump. Reality had caught up to the hype, I thought. Except I was wrong, of course, because then this hype arrived:

Google’s earlier exponent improvement had already inspired the same enthusiasm:

I also saw this cunningly hilarious comment:
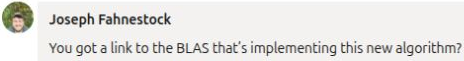
I am no expert in fast algebraic matrix multiplication algorithms, but I had dim memories of them being very impractical.
2 It Got Weird After Strassen
Back in the days when studying computer science was still a thing, Strassen’s matrix multiplication algorithm was sometimes taught in algorithms classes. It is pretty weird when you first see it.
It lets you multiply two matrices, by recursing into only seven matrix multiplication subproblems of size . This is weird because there are 8 block-multiplies to do, but you can get away with just 7.
This results in the funny time for Strassen’s original matrix multiplication algorithm. Apparently, this algorithm does get some use in practice.
Now, far beyond my pay-grade, people have hammered away at getting faster algorithms. If we are very optimistic about making these algorithms practical, they still run into an extreme trade-off between the reduction in exponent and the constant inside the big-Oh.
A nice example: improving Strassen’s algorithm to one taking time, i.e. an exponent improvement of roughly , increases the leading constant inside the big-Oh by a factor of about . For this to have a hope of helping in practice, we’d need , or .
That is a big matrix. It would have something like entries, where is the number of atoms in the visible universe (see this lovely paper for more details). This is the realm of galactic algorithms!
3 The Final Insult, Courtesy of OpenAI
OK, so those old-hat fast matrix multiplication algorithms are out, but now we have OpenAI’s breakthrough time algorithm. Perhaps this algorithm is ripe for porting to GPUs and hastening the singularity?
Well, it seems OpenAI gave an existence proof for such an algorithm. We have a proof that a fast algorithm exists. We don’t have the recipe! This is before even worrying about what the leading constant is.
Now, maybe an AI will discover a practical fast matrix multiplication algorithm, but this is most definitely not the one that will cause the foom.
P.S. Funnily enough, on the day I write this a biological intelligence calling itself Rafael Pass has given a constructive version of OpenAI’s algorithm (sadly, he explicitly rules out firing it up on GPUs just yet, remarking The algorithm remains “galactic”: the constants hidden in the notation are enormous)